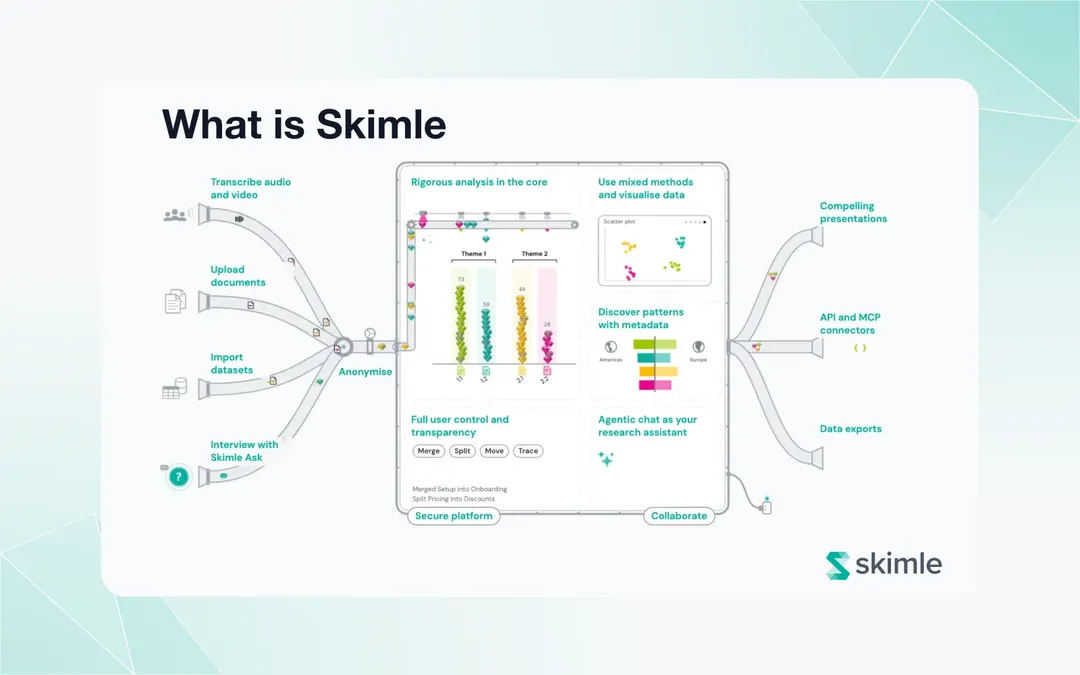
When you analyse dozens of interviews, the raw output can include thousands of categorised insights. With comprehensiveness a key goal in Skimle analyses, some insights will be tangential to your core interests. To avoid this trade-off between comprehensiveness and relevance, we show you the best insights and quotes first.
Continuous improvements to your user experience
During the last week, we tweaked how Skimle shows insights to you. We are building a professional tool with the intent of saving your time and allowing you to handle larger bodies of knowledge with less effort. Large langauge models enable us to create small improvements everywhere, such as our automatically suggested labels in manual coding. One such area is how we order insights in the user interface and exports.
More than just stitching quotes together
Skimle analyses identify relevant content out of your documents, combines quotes into document-specific insights and rolls those up into cross-document thematic categories. But we do much more. Once insights have been assigned to categories, we check every quote: does it really illustrate the insight AI model assigned it to? If the answer is no, the quote with poor fit is hidden so what you see is on-topic.
Insights are ranked by relevance, not by ID
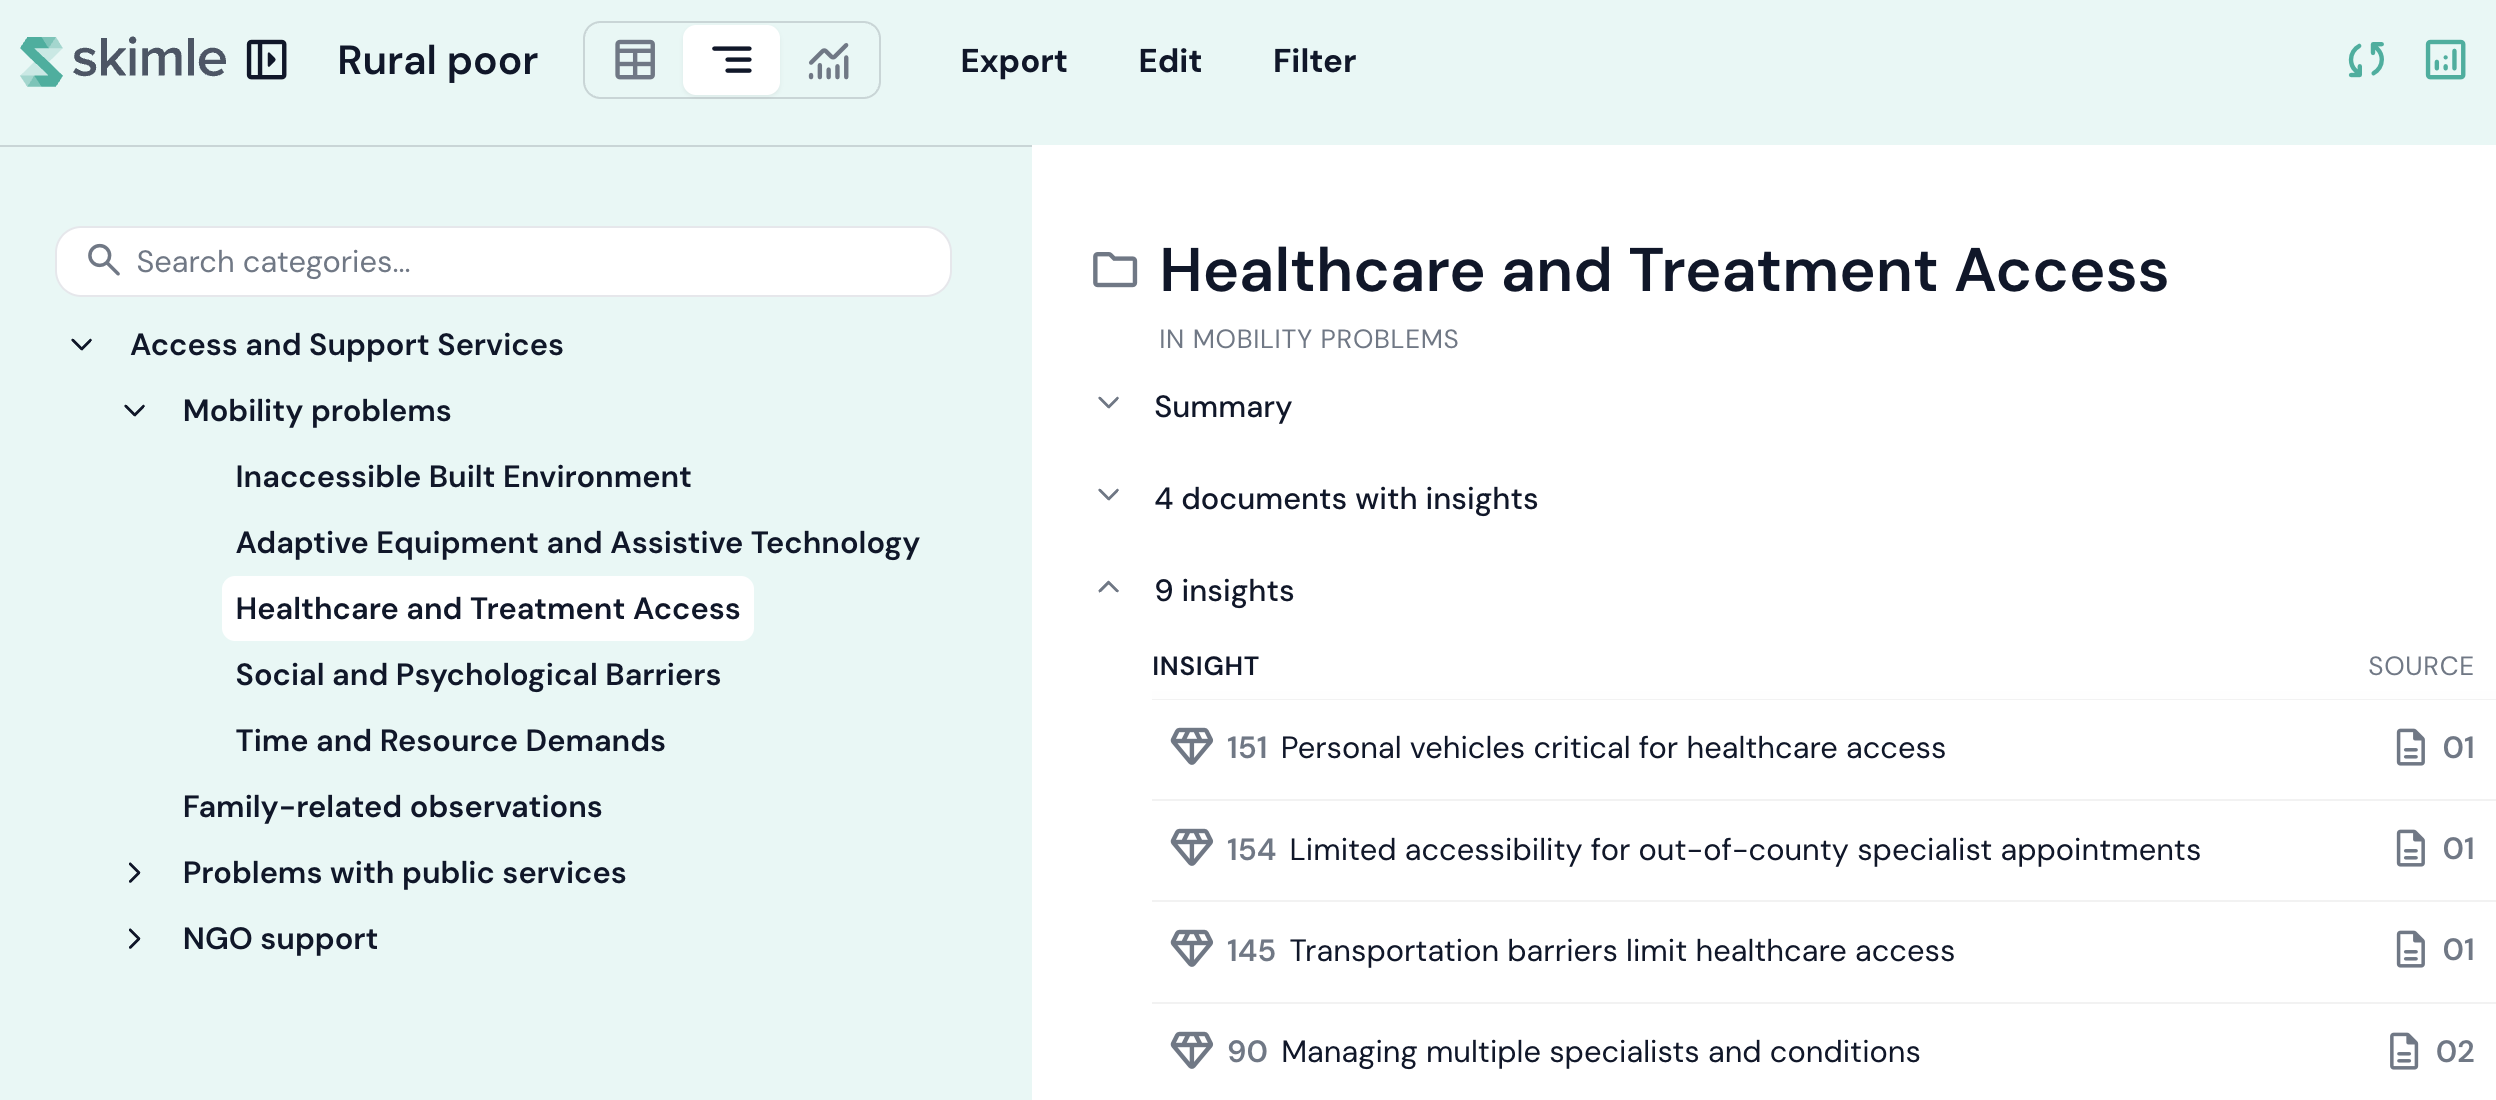
Insights assigned to each category get ordered based on their relevance. Our assessment pipeline ranks insights based on three factors: whether the quotes are semantically close to the category, whether they are distinct from neighboring categories and whether they are supported by rich, specific evidence. The goal is simple: when you click into a category, the most useful stuff should already be at the top of the screen.
What changed in this update
We did three small but impactful changes to the service:
1. Smarter sorting that knows the neighborhood. Our ranking now factors in distinctiveness from peer categories, not just thematic fit. If your category is "Complaints about user interface," Skimle now prioritizes quotes that are clearly about the UI and clearly different from complaints in adjacent categories.
2. Intelligent ordering everywhere it matters. Until now, this thoughtful ordering only showed up in the table view. With this update, both the categories view and the export center order insights based on their relevance to the category.
3. Ordering is updated when categories change. Previously we rank-ordered insights only after the initial analysis. Now every time you are done editing and recreate category summaries, we detect each category with new insights and run the ordering algorithm.
What this means for your workflow
When you open a category in Skimle's categories view, the insights at the top are now the ones that:
- Clearly belong in that category (high fit)
- Are distinct from what neighbouring categories cover (high distinctiveness)
- Are supported by rich, specific evidence (high quote richness)
- Contain genuinely interesting and non-obvious findings (high interestingness)
The same ordering carries through to your Word and PowerPoint exports. When you generate a report, the most relevant insights come first in each category section.
The "Quote mismatch" tags give you a lightweight quality-control layer. You can filter by tag to review flagged insights in a batch, decide whether the labels need revision, or confirm that your own judgement (perhaps informed by off-record context) stands. One of Skimle's core principles is that every insight traces back to source data. Smart ordering helps maintain transparency and put you in control, while preventing you from drowning in your data.
It is still early days: Every week comes with a better Skimle
We are excited about continuously improving your experience with our service. Sometimes it is new functionality or even entirely new services like Skimle Anonymise. Other times, we fix the algorithms under the hood, as I described in this post. Next 3-4 weeks will be all about usability improvements and better navigation. We are already testing direct upload of video and audio files to new projects and providing tools to efforlessly move and combine categories right in the category view. We are also working on a "project control panel" that allows you to easily create new categories for a subset of documents. For example, you will be able to easily specify distinct analyses for your interviews and field notes within the same project.
About the Author
Henri Schildt is Professor of Strategy at Aalto University School of Business and co-founder of Skimle. He has published dozens of peer-reviewed articles using qualitative methods, including work in Academy of Management Journal, Organization Science, Organization Studies, and Strategic Management Journal.
Henri developed Skimle after years of frustration with existing qualitative analysis tools that failed to leverage AI's potential while maintaining academic rigour. Google Scholar Profile